Redundancy
Streamer autonomy allows broadcasting and archive recording to continue during a central outage. Redundancy keeps management available while the failed machine is restored.
This page describes the components of a redundant installation, how many instances of each to run and what a second instance changes. For configuration, see A central group on separate servers. For state storage and guarantees, see Components and reliability.
What is made redundant and what is not
Only the control plane needs redundancy. The media path is already independent: the streamer ingests the source, transcodes, records the archive and serves the stream itself. Playback at the streamer's public address does not require media proxying through central.
The rule for a redundant installation is therefore: central and streamers run on separate machines. A local streamer inside the central process is unsuitable: its streams stop together with central.
The mandate: which instance does the work
Several central instances using one database form a group. Some work can safely run on all instances at once; other work cannot: two layouters could change the placement of the same streams concurrently.
Work like that is done by one instance in the group — the one that has taken the mandate for it. Three properties of a mandate determine everything about how the group behaves under failure.
- PostgreSQL issues mandates, not the config. An instance's config contains only a role claim: "this machine is ready to do this work". Enable the component on several instances so another can continue the work.
- A mandate is released when the database connection ends. A dedicated database connection holds it: when the session ends, another instance acquires the released mandate. No timeouts, stuck-executor handling or manual confirmation are needed.
- Each acquisition has a number: an epoch. It increases when the holder changes and is checked on every write. An instance that continues working after losing its mandate has its writes rejected rather than changing placement with stale results.
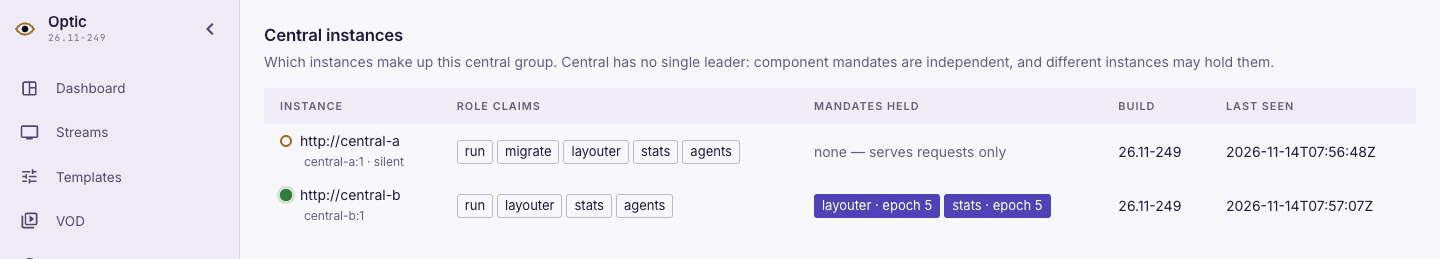
Mandates are independent. Central has no single leader: different instances may handle placement and statistics, and this is normal.
Who holds what is visible in the console: Cluster → Central.
Components and their count
Central is not one process with one role but several different jobs, and they are made redundant in different ways.
| Component | How many executors | What the second instance gives |
|---|---|---|
| PostgreSQL | One cluster | Made redundant by the database itself, not by Optic |
| Request handlers | Every instance | The control plane survives the loss of a machine |
| Agent connections | All instances with the agents component |
The agent reconnects to an available central using the same URL |
| Current state | The stats mandate holder |
A replacement holder; statistics are collected again |
| Layouter | The holder of the layouter mandate |
A replacement executor with no operator involved |
| Schema migrations | Exactly one instance | Nothing: two migrators are a race, see below |
| Session harvesting | One executor per streamer | The streamers of a lost instance move to a live one |
| Periodic jobs | All of them | Nothing: one of them does the job anyway |
| Operator entry point | One address | — |
| Streamers | As many as broadcasting requires | Their redundancy comes from placement, not from here |
What follows is what each of them does and why the count is what it is.
Request handlers
This is what the operator and the cluster see as central: the console, the management API, the player front end, the metrics export and the incoming sync from streamers. A handler holds no state of its own — everything lives in PostgreSQL — so there may be any number of instances, and any of them can answer an operator's request.
Streamers use a list of addresses rather than a load balancer: each streamer contacts the first address, switches to the next after a failed request and returns to the first when it responds again. The initial list is configured on the streamer; further addresses come from central. Every sync response includes the group roster, so adding a third instance requires no streamer config changes — see The streamer learns the group on its own.
The second instance gives two things:
- The control plane survives the loss of a machine. The operator and the streamers move to an available instance.
- Upgrades without a window of downtime. Instances are upgraded one at a time.
Agent connections
Each central with the agents component accepts endpoint connections and handles them in its own process. An agent has one URL; its DNS name resolves to several central instances. If the connection or endpoint protocol fails, the agent tries another IP without changing the URL. A working connection stays on the instance that accepted it.
You can send a command to an agent through any central: the request reaches the instance with its connection. The streampoint media tunnel connects the agent to its assigned streamer. Initial endpoint and streampoint configuration is described in receiving video through agents.
For address settings and failover checks, see the central group.
Current state
Central does not read the current state shown in the console — which streams are running and how many playback connections there are — from the database. The database stores what should be (settings, placement) and what has already happened (closed sessions, journals); current state is held in memory.
Current state is shared by the group and held by the stats mandate holder. Other instances contact the holder over the network at its advertised address. All streamers are therefore visible from any group address, even when they report to different instances.
When the holder changes, statistics are rebuilt, not transferred, from the next sync requests, within seconds. During that interval, the console shows incomplete figures: a stream may already be broadcasting without appearing in the active list.
The archive, session records and settings are not lost: only current-state data is incomplete. During the first half-minute after a holder change, console figures do not represent the cluster's full state; reports of "missing streams" reflect statistics recovery.
Layouter
The layouter decides which stream runs on which machine. Running two layouters over one database would allow concurrent placement decisions and writes to the placement journal, moving streams between machines without a reason.
The layouter mandate holder executes the runs, and each write is checked against its epoch. All group instances should claim layouter: claiming it on only one leaves the group without placement when that machine fails.
An instance not holding the mandate is complete in every other respect: it serves the console, the API and streamer sync. Nothing has to be switched on during a failure — the mandate moves by itself.
Schema migrations
The one job no mandate guards is applying migrations at start. Two processes starting at once will race each other through them, so the migrate role is claimed by exactly one instance and the rest start after it.
An empty central.components object preserves values from earlier layers. If no layer sets migrate, it is enabled by default. A second instance started with a copy of the first instance's config becomes a second migrator.
Session harvesting
Who watched what — the sessions — is not something central receives passively: it pulls them off the streamers itself, over a continuous channel to each streamer.
Work is divided by streamer: one executor receives a streamer's data at a time, and different executors may serve different streamers. After an instance fails, another receives data from its streamers; session accounting is preserved.
Downtime loses no records either: a streamer keeps its session journal for several days, and harvesting continues from where it stopped. An hour of downtime means the records arrive later, not that they will not arrive.
Periodic jobs
The remaining background work runs on a schedule: journal retention cleanup, VOD storage accounting (deactivating storage on missing machines and expiring unfinished uploads), and clearing the status of streamers that stopped reporting.
These jobs run on all instances: repeating cleanup and storage accounting does not change the result.
There is no need to spread these jobs across instances by hand, nor to switch them off anywhere.
PostgreSQL
The database stores the group's configuration and registries. Its redundancy is not provided by Optic. All instances need one logical cluster reachable at one address; its fault tolerance is handled by the database itself, using a replica with failover or a provider-managed instance.
Two independent database servers are not redundancy but two separate installations: their placement and their streamer registry will diverge.
Backups are still needed: a spare protects against the loss of a machine, not against a mistaken deletion — see Backup and restore.
The operator entry point
The operator needs one address that finds an available instance by itself: a DNS name with failover, or a load balancer in front of the group.
Streamers do not go through it — they have a list of addresses of their own, and an extra intermediary on the sync path only adds a point of failure.
Streamers
Streamer redundancy depends on placement, not the number of control instances: a stream assigned to more than one machine survives the loss of any one of them. This is separate from central redundancy.
Scenarios
An instance fails
Everything happens by itself, with no involvement.
- Streamers move to the next address on their list after one failed request. They need no reconfiguring, and there is no break in broadcasting.
- The mandates of the lost instance move to a live one within seconds. Placement keeps working, new streams are placed as usual.
- Statistics are collected again. Console figures are incomplete for half a minute while statistics recover.
- The operator works through the same address with the same password. The state lives in the database rather than in the lost machine: the streamer registry, the settings, the placement are all in place.
If the instance with the migrate role fails, another must take that role during recovery so the next upgrade can apply migrations.
An instance comes back
Coming back is not an emergency operation and needs no window of downtime.
- Mandates stay with their current holders. A working holder continues its work; another holder change would require statistics to be rebuilt again.
- Streamers resume sync with their preferred address within five minutes, using a normal sync request. The address order is the operator's preference, and it is restored automatically.
The group works in any arrangement of the mandates, so there is no need to restore the original one.
A planned upgrade
Instances are upgraded one at a time, and it is the same scenario, only controlled: while one is being upgraded the streamers work with the other. The mandates move twice in the process — once per restart — and both times by themselves.
Losing the database
The control plane stops entirely: there may be any number of instances, but they have one state between them. While the database is unavailable the console and the API serve no requests, and new streams are neither created nor placed. Nobody holds a mandate during that time — the database is what issues them.
Broadcasting continues: streamers operate autonomously, broadcasting, recording and serving video without contacting central. Losing the database therefore interrupts management, not broadcasting.
Recovery is the database's own business (a switch to a replica) or a restore from backup; see Backup and restore.